
Oppologist
One of the strangest limitations of current LLMs is that a model may handle billions of conversations, but each interaction is largely a lost opportunity for structured learning.
If the LLM gives a bad answer, fails to search, treats random Reddit speculation as evidence, or confidently guesses, correcting the LLM may improve the rest of that conversation but it does not update the model itself.
It will happily apologise and then make the same type of mistake again tomorrow and the day after.
The obvious next step for LLMs is continual learning with specialised agents that kick in when a user is frustrated; not necessarily changing model weights live, but deliberately turning real interactions, corrections and failures into structured training data for subsequent specialised training.
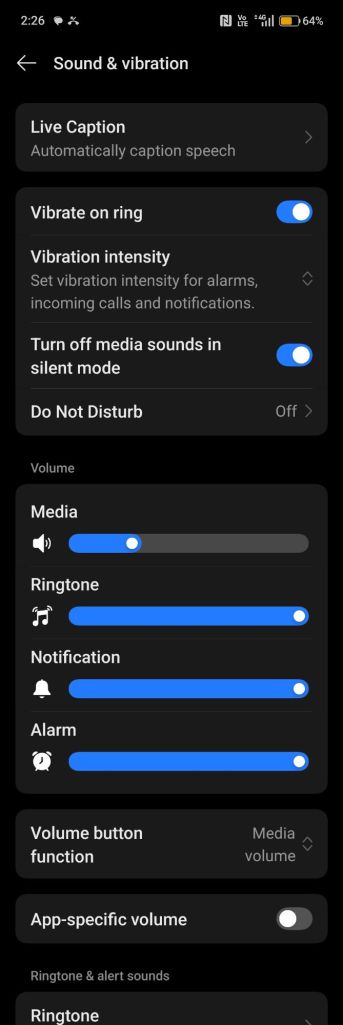
Today I used GPT to diagnose why my Oppo phone stopped making sounds of any sort through the inbuilt speaker.
Dozens of screenshots of settings were sent through. Finally I lost my shit and just reset the phone, which fixed the problem
I asked it if there is any evidence of that elsewhere and yes all over Reddit apparently.
So why didn’t it search before trying to help me?
Then I asked it what the underlying problem was. It had the answer of course, which turns out to be pure speculation from some Redditer.
Fuck me….
 offshore westerly
